The allowance in this demonstration is 24 invented request units, with no refill. It is not tokens, money, real account usage, or a measure of how long a plan will last. Twenty actions with predetermined failures were replayed against a local fake processing function under two authored comparison policies. No real service or AI model was called during measurement. When one click becomes several requests, where should the app stop, and what should it tell the user?
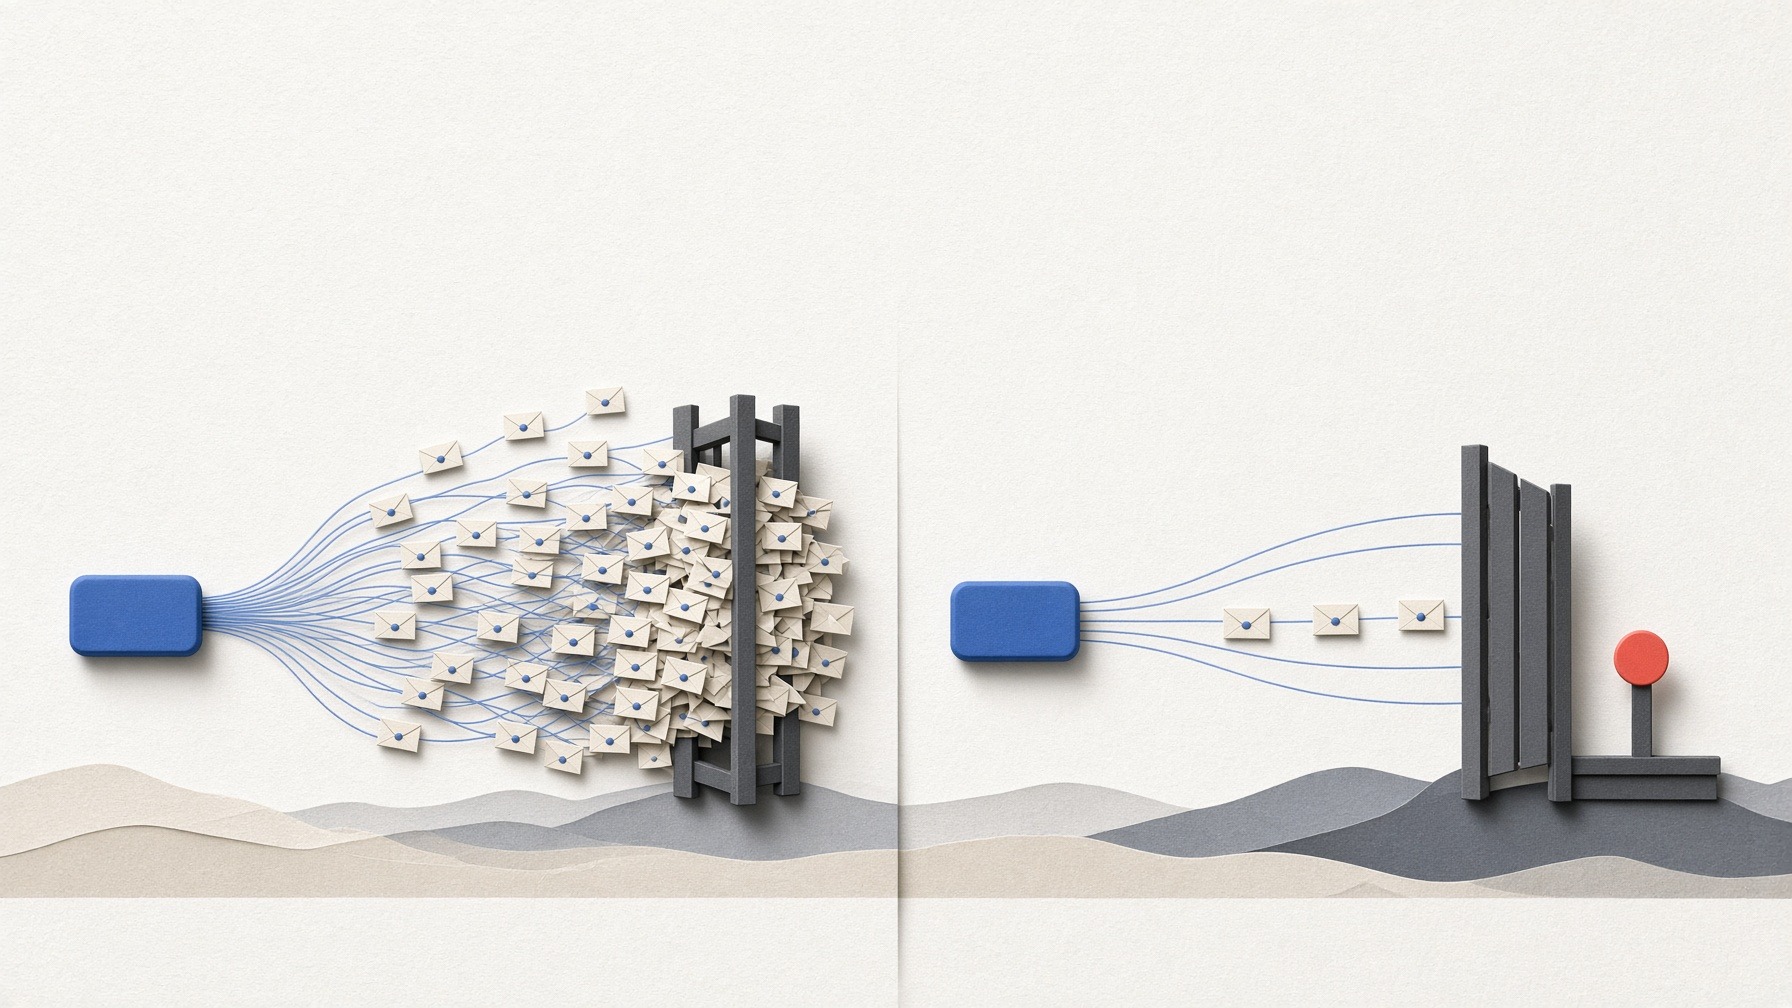
This is a conceptual illustration, not experiment evidence or a depiction of the actual request counts.
In this article
What the sources say: does no response mean the save failed?
HTTP standard RFC 6585 §4 defines 429 as too many requests within a period of time. The response may say how long to wait before trying again, but the standard does not define how requests are counted. A 429 response must not be cached for reuse. RFC 9110 §9.2.2 says that automatically retrying a request that could cause another effect requires knowledge that the operation is actually idempotent—repeating it has the same intended effect—or that the original request was not applied. Losing a save response is not enough reason to resend it blindly, and adding an arbitrary key does not make it safe. The recorded source-check date for both sources is October 16, 2026.
This article counts action → request → effect → confirmation received by the app separately. An effect is a change such as a saved record. A save can succeed even when its confirmation goes missing.
Recorded observations: 20 actions, separate ledgers
On October 17, 2026, one author-specified synthetic scenario was run on macOS 27.0 with Python 3.9.6. A fake processing function played the server's role; no real server or network was involved. In the observations below, “server” means that fake. Codex, an AI coding tool, assisted with writing the code; no model participated in the replays.
A was a deliberately built comparison baseline that retried every error immediately. It had no app-level stop, so the test harness—the setup limiting execution from outside the app—allowed at most 8 attempts per action, including the initial request. Virtual time advances in the simulation ledger; it is not time actually spent waiting. B's settings were:
- Per action: at most 3 attempts, including the initial request, and 20 virtual seconds.
- Overall: 40 requests, including at most 12 retries, and 300 virtual seconds.
The design permits an action's initial request after the retry budget is exhausted, provided the other limits allow it. However, this measurement did not reach that budget or trigger the overall request, time, or allowance-exhaustion stops. These are experiment settings, not recommended retry counts.
B also respected server wait instructions, reused successful read results, shared identical reads already in progress, and used save-operation keys that the fake server was built to recognize. Because several controls changed together, their individual effects cannot be isolated.
The fake deducted 1 unit for every admitted request, even if it ended in an error or timeout. A request returning an existing save through the same key also consumed a unit. Once the balance reached 0, later requests were rejected without any deduction. This setting cannot be read as a real provider's billing or allowance rule.
| Results from one scenario—all allowance units are invented | A | B |
|---|---|---|
Requests / 20 input actions |
119 / 20 |
22 / 20 |
Request composition |
20 initial + 99 retries |
14 initial + 8 retries |
Units consumed / starting units |
24 / 24 |
22 / 24 |
Units remaining / starting units |
0 / 24 |
2 / 24 |
Uncharged allowance-exhaustion rejections / all requests |
95 / 119 |
0 / 22 |
Extra saves beyond the intended operations |
1 |
0 |
Confirmed completions / input actions |
6 / 20 |
15 / 20 |
Final messages matching the pre-written text/evidence rules / all final messages |
6 / 20 |
20 / 20 |
The paired duplicate-save case is W1. The counts are not rates across three equally exposed save intentions. W3, discussed below, never reached A's save step because A's allowance was already empty.
The actions have identifiers A01–A20, but did not run in numerical order. A01 and A02 started together; permanent error A16 was placed after A03. Policy A spent 8 units each on A16 and A04, and had spent 23 through A07. Its first timeout on A08 used the final unit, at A's virtual time of 3,100 milliseconds. B used 9 units through A08 and 13 afterward, leaving 2 at the end. The 97-request gap and 2-unit gap are final differences under this order, cap, and charging rule, not real-allowance depletion rates.
A08's remaining 7 requests and all 88 later requests were uncharged rejections. Of B's 9 additional confirmations, 7 were on actions whose processing scripts A could not execute because its allowance was empty. The other two were A04 and A08. On A04, A sent 8 requests without waiting; B waited and confirmed completion in 2 requests. On A08, A's follow-up attempts were rejected, so this is not a paired test of timeout retries with allowance available. The completion totals are valid, but are not success rates across equally executed failures.
B's completions include 5 actions that reused successful read results and 1 that shared a read already in progress. Each count is out of the 20 input actions; these completed with confirmation without new requests. B actually stopped on permanent error A16, the 3-attempt limit on A11 and A12, unconfirmed save A13, and A17's 120-second wait that could not fit within the 20-virtual-second action limit. This does not mean every configured cap fired.
Each policy was replayed once more in a fresh process. For each pair, 9 of the 9 compared files matched. This checks consistency with identical inputs; it does not add independent samples. The virtual end times were 13.600 seconds (13,600 milliseconds) for A and 14.548 seconds (14,548 milliseconds) for B, so the results do not show B running faster.
Before measurement, preparation went through 3 reviews and 2 revisions. Fixes addressed a wait calculated 1 millisecond too short, a checker that accepted a false failure message after a successful response, and missing stop records, among other issues. Failed versions were preserved, and the code, inputs, and evaluation rules were frozen before measurement. The scenario was not changed or remeasured to suit the results. A separately kept experiment record, an English technical document, retains all 20 action rows and the revision history.
Saved, but the app does not know
The three save intentions were labeled W1, W2, and W3. Both policies sent 2 requests for the first intention, W1. A created 2 saved records. B resent the request with the same save-operation key, and the fake server returned the result of the 1 existing save. That replay also consumed 1 unit. W2 had identical content but represented a separate intention, and each policy created 1 record for it.
For W3, which had no save-operation key to protect it, B saved 1 record but received no response, so it did not resend. The complete recorded English output was:
No confirming response arrived; the save outcome is unknown. Automatic retries stopped. Stop reason: UNSAFE_WRITE. It may have saved and will not be resent automatically.
The test ledger records the save; the app does not know it happened. All 8 of A's W3 requests were rejected without charge because the allowance was empty, producing 0 saves. This is not a paired comparison of duplicate prevention. Stopping automatic resends still leaves the possibility of a duplicate if the user submits the same save again. That is a design risk, not a measured result about repeated clicking. The app should not invite resubmission without confirmation or claim that an untested refresh path can confirm the save.
Both policies created 3 saved records in total, and each had 1 record without a link to received confirmation. However, A confirmed its second W1 save while the first remained unconfirmed. B left its only W3 save unknown. “Confirmed completion” does not mean “saved once,” and B's 0 duplicates do not mean every save was confirmed.
In A, the harness cut off 14 of the 20 actions, yet the app still displayed “Trying again…”. That was the deliberately authored baseline's behavior. B's 20/20 final-message score measures agreement with the pre-written text/evidence rules and records, not how well people understood the messages.
My view: questions to ask the AI that builds the app
The earlier article on scheduled agent operations distinguished registration, execution finishing, reporting, and trusting the result. Here, the distinction is between requests, effects, and confirmations. Neither experiment establishes that a local limit is a provider-enforced spending cap.
You can paste the following request into the AI tool building your app and ask for evidence rather than assurances. It has not been tested for usability or savings. This is an English adaptation of the Korean edition's checklist. Here, “server” means the server your actual app uses.
Review this app's retries.
1. Where do the app and its libraries each send requests again?
2. What are the per-action attempt and time limits, including the initial
   attempt, and the overall request and retry budgets?
   Explain why those values were chosen and show evidence that they
   actually stop the retries. Separate configured limits from tested stops.
3. Does the app respect server wait instructions? If the wait cannot fit
   within its limits, does it stop?
4. Are only successful read results reused, with matching user, content
   version, and expiry rules? Are errors and 429 responses kept out of reuse?
5. Does the server support the save-operation key? Do separate operations
   get separate keys?
6. Does the app distinguish confirmed completion, previous/shared results,
   failed reads, unconfirmed saves, and actions not sent—and explain the stop
   reason and that automatic retries have ended?
   Does it avoid inviting resubmission of an unconfirmed save?
   Do not suggest a check that creates no new save until that path is verified.
Record action → request → effect → confirmation.
Record unconfirmed outcomes as unconfirmed.
What was not verified
The experiment did not establish real provider limits, depletion rates, prices, bills, or how long a plan lasts. Coding-session usage and cost, and total labor time, were not measured either. Having 0 provider calls during measurement does not mean the total cost was zero. No capacity forecast worksheet was produced.
- Production network reliability, a universally appropriate retry count, the causal effect of each control, the frequency of AI-generated code defects, and a guarantee of exactly one save were not established.
- The effect of spreading retries across multiple users, nested app/library retries, and recovery in a circuit breaker that blocks requests during failure and probes before resuming were not measured.
- Human understanding, reductions in repeated clicking, and a refresh-based path for confirming saves were not tested.
The measured scenario did not trigger B's overall request-limit, time-limit, or allowance-exhaustion stops, or exhaust the retry budget. It did not test expiry of successful read results, conflicting content under the same key, or every priority when several limits apply together. This fake checks allowance before looking up a save-operation key, but key replay to confirm a save after allowance exhaustion was not observed either. Separate preliminary checks are not counted as observations from this scenario. Changing the input order or fake allowance rules could change the results.
AI assisted with research and drafting. The author reviewed the final manuscript and directed the revisions.


답글 남기기