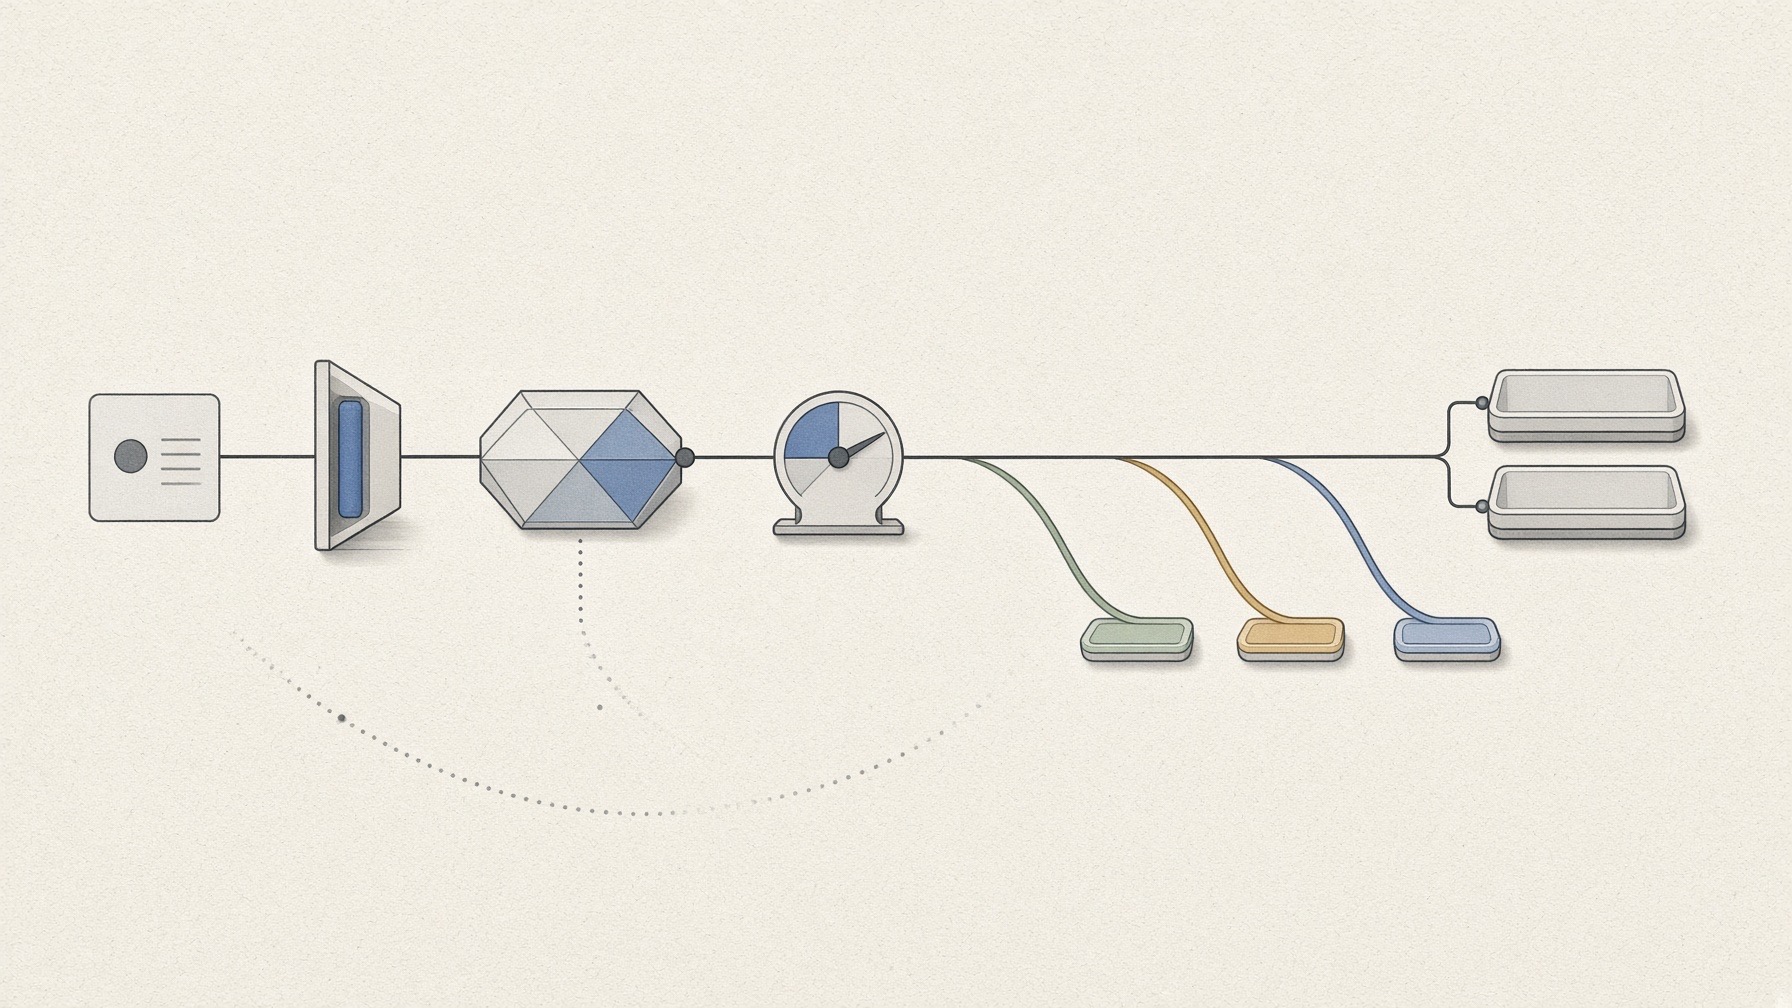
Trusting a scheduled run should not mean that its report merely sounds plausible. In this article, trust means being able to reconstruct which input was used, whether the job stayed within its declared authority, whether its result passed the check, and whether it stopped when required.
The reason for this distinction is simple. A registered schedule, a finished run, a written report file, and a report you may trust are four different states. OpenAI’s Scheduled tasks guidance, checked on September 12, 2026, separates the saved prompt from the trigger and describes conditions for desktop tasks that use local files. It also recommends narrow access and review of early runs. The checked page does not establish output correctness, general retry or overlap behavior, a per-run spending cap, or universal mid-run cancellation. I therefore rehearsed the operating controls with synthetic data and a logical clock—a fixed event list that advances without waiting for future wall-clock time—instead of enabling a real schedule.
In this article
Yesterday’s report can still look convincing
No real AI was called. The central test used a canned candidate to produce a deliberately stale but internally plausible report. The verifier expected snapshot SYN-20260902; the candidate actually read SYN-20260901. The report based on the older file did not look obviously wrong.
Writing, however, was not acceptance. The verifier compared an independently frozen expected snapshot ID and input hash with the identity reported by the candidate. Its verification record contained binding_mismatch. The candidate never reached the accepted directory; it moved to quarantine, while the result a report reader would see was a rejection record labeled rejected_binding_mismatch.
This is a planted control, not a reliability rate. It shows that this verifier rejected the known stale input. It does not show that an AI recognized staleness.
What was tested without a real schedule
The experiment used a canned deterministic candidate and made no external model call. Its purpose was to inspect the recurring-job wrapper and verifier, not a real AI’s writing ability. A driver, standing in for the trigger, advanced through a finite list of logical events without waiting for future wall-clock time. The candidate received the selected synthetic JSON and run identifiers. A separate verifier used independently frozen bindings and a content oracle to check input identity and exact counts and changes. Only when that check passed did a writer promote the staging result to an authoritative accepted artifact.
Declared authority, enforced channels, and recorded observations were kept separate. The task specification declared allowed inputs and outputs. The local wrapper exposed no network, browser, subprocess, scheduler, or provider capability to the candidate. The ledger recorded decisions visible to that wrapper. This does not prove operating-system isolation or a vendor sandbox. Those restrictions applied to the candidate; the wrapper itself wrote files. The run was read-centered, not read-only, and wrote baseline, staging, verifier, accepted, rejected, quarantine, ledger, inventory, and summary artifacts inside one isolated run root.
Results across the 12 cases
Each frozen case was scored against its own expected outcome or outcomes, not averaged into a trust score.
- Accepted: the fresh baseline, changed current snapshot, and new-day no-change report passed verification.
- Blocked before candidate work: missing and malformed sources failed, and redelivery of the same operation created no second artifact.
- Conflict and retry: an overlapping request with a different binding was recorded as a conflict while the original binding remained accepted. A planted transient post-staging failure was quarantined, then accepted after one simulated retry. A persistent error stopped at the retry ceiling; a non-retryable error stopped with its separate
stopped_nonretryabledisposition. - Separate stops: C10’s planted case-local budget refusal occurred before start with zero candidate calls and produced
stopped_local_budget. Future-run prevention, active-local interruption, and simulated read-policy revocation each left a distinct record.
All 12 logical cases matched their frozen expected dispositions. Candidate invocations were the planned 11, below the whole-series hard ceiling of 20. C10’s pre-start refusal did not consume or prove that ceiling. The finite replay took 25.229 milliseconds, and the hash-chained 47-event ledger verified. That timing describes a small local fixture and canned candidate, not the speed of a real reporting job.
“Stop” was not a single button
Preventing a future run was confirmed by a marker persisted before the due event and by the absence of later work. Interrupting an active local step was confirmed by a request and acknowledgement, quarantined partial output, and no promotion. Simulated local read-policy revocation evaluated the new policy hash before source access and created no cached fallback. None of these tested a vendor queue, remote cancellation, or account-permission revocation.
Why the cost record has five lines
- Provider calls: 0 at the wrapper boundary
- Additional-charge observation:
not_checked, because no billing surface was accessed - Usage value: unavailable
- Local invocation ceiling: 20, controlled only by this driver
- Provider-enforced cap: not verified
That record does not support a “zero cost” claim. The local ceiling of 20 candidate invocations was not a provider budget cap. You can enforce only the limits you actually control, and the record must say so.
Seven questions before enabling recurrence
Before enabling a recurring automation, try answering each of these in one line:
- Exactly which input does it read?
- Which actions are allowed and forbidden?
- Where are candidates kept separate from accepted results?
- What evidence defines success?
- Which spending or invocation limit can you actually enforce?
- Which errors may retry, and how many times?
- How do you separately prevent future runs, interrupt an active step, and revoke reading?
A blank answer is an operating-design gap, not a model-intelligence problem. The conclusion here is deliberately conditional: this local wrapper and verifier behaved as specified on the frozen synthetic cases. NOT TESTED: AI output behavior; real scheduling; vendor trigger, retry, overlap, cancellation, or delivery behavior; OS or vendor isolation; distributed exactly-once delivery; zero cost; a provider spending cap; or readiness to activate a real job.
AI was used to assist with research and drafting. The author independently verified and edited the final article.


답글 남기기